
PowerFM is an open-source repository for foundation models in the power and energy domain. It both maintains original projects and collects community-contributed open-source projects, featuring fine-tuned and domain-trained models for tasks like load forecasting, fault detection, grid simulation, and agent control.
Explore the Dataset and Benchmark for Power System Foundation Models Across Multiple Scales and Topologies
OpenPowerBench is a first-of-its-kind open-source, multi-task, cross-temporal dataset designed to support training and evaluation of foundation models in power systems. OpenPowerBench includes both topology-dependent tasks (e.g., power flow, optimal power flow, contingency analysis) and topology-independent tasks (e.g., load forecasting, price prediction), supported by a modular data generation pipeline for scalable benchmarking across synthetic and real-world scenarios.


GridLDM is a unified latent diffusion framework for controllable power-system time-series generation across heterogeneous domains, including EV charging, commercial load, wind generation, solar generation, and transient voltage response. GridLDM learns a shared latent generative prior and uses natural-language prompts with cross-attention to condition synthetic time-series generation across different data lengths, temporal structures, and operating contexts.

GridFM Community The GridFM project pioneers the concept of FMs for the electric power grid to be trained on grid data – as opposed to text data – with the overarching goal to develop the underlying technology to cope with the increasing complexity and uncertainties of a faster growing grid (e.g., due to hyperscalar data centers, crypto mining etc.). More information about GridFM Community can be found here
mAIEnergy is a unified, open-access multimodal corpus designed to support Continual Pre-Training (CPT) of Large Language Models (LLMs) and the development of Retrieval-Augmented Generation (RAG) systems in the energy domain. The dataset integrates heterogeneous energy-related information into structured, machine-readable formats, enabling seamless integration into modern AI and multimodal learning pipelines.
The corpus is organized into four top-level modules—textual, numerical, geospatial, and imagery—each accompanied by structured metadata and reproducible processing workflows. In total, the dataset contains approximately 50,000 textual documents, 20,000 images, 25 million numerical time-series records, and 2 million geospatial and relational data entries, primarily focusing on the European energy system.

Detailed datasets and fine-tuned models can be found below:
- Dataset: Zenodo Repository
- Trained/Fine-tuned Models: Hugging Face Model Hub
Datacenter Siting Assistant: Solvtra is a tool leverages RAG by incorporating datacenter-specific data, including local regulations, environmental reports, and infrastructure details. As a result, it can provide detailed information for potential datacenter locations, such as land and electricity prices, and generate a map illustrating existing datacenter sites and relevant infrastructure.
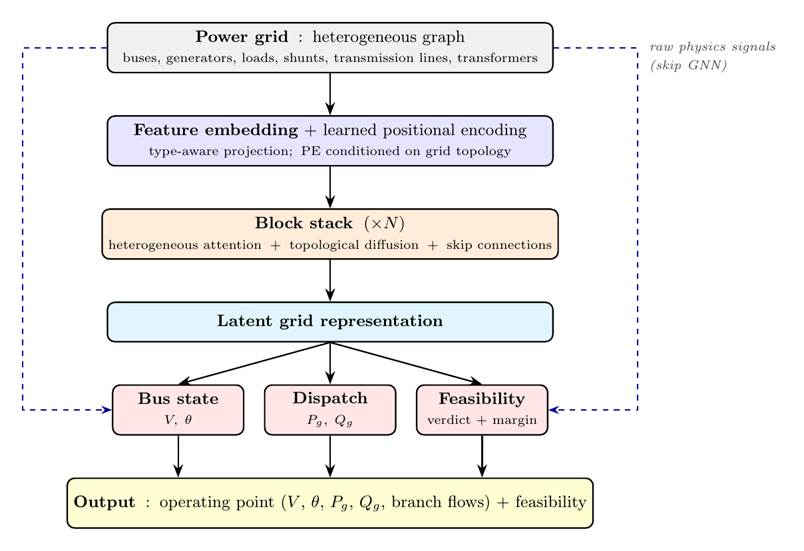
GridSFM is an open foundation model for approximating AC optimal power flow across different power-grid topologies. It represents the grid as a heterogeneous graph and predicts operating states such as bus voltages, generator dispatch, and branch flows, supporting scenario screening and warm-starting conventional AC-OPF solvers.

Code, checkpoints, and the paper can be found below:
- Code and Data Pipeline: GitHub
- Released Checkpoints and Datasets: Hugging Face Collection
- Paper: GridSFM: A Foundation Model for AC Optimal Power Flow
PriceFM is a foundation model for probabilistic day-ahead electricity-price forecasting across connected European market regions. It combines a Mixture-of-Experts feature projection with a sparse graph mask informed by transmission topology to generate quantile forecasts across regions and lead times.

The pretrained model, dataset, and paper can be found below:
- Pretrained Model: Hugging Face Model Hub
- Dataset: Hugging Face Datasets
- Paper: arXiv:2508.04875
PowerGridQA is a power-system question-answer dataset covering dynamics, operations, reliability, and reasoning. The repository reports 28,852 question-answer pairs, supporting the training and evaluation of language models on power-domain knowledge.
- Paper: IEEE Xplore
PowerCodeBench is an execution-validated benchmark for LLM-generated power-system analysis code. It is built on executable pandapower programs with reference results, and the repository describes 2,000 tasks.
- Paper: Research Paper
Note: Code, model, and dataset licenses may differ between projects and between components of the same project. Check them independently before reuse.
We welcome contributions! Please see our Contributing Guidelines for details.
This project is licensed under the MIT License - see the LICENSE file for details.
Shaohuai Liu, Yuting Cai, Alban Puech, Costas Mylonas, Magda Foti, Qian Zhang
- All contributors who help make this project better
- The Power and AI Initiative (PAI) at Harvard SEAS